










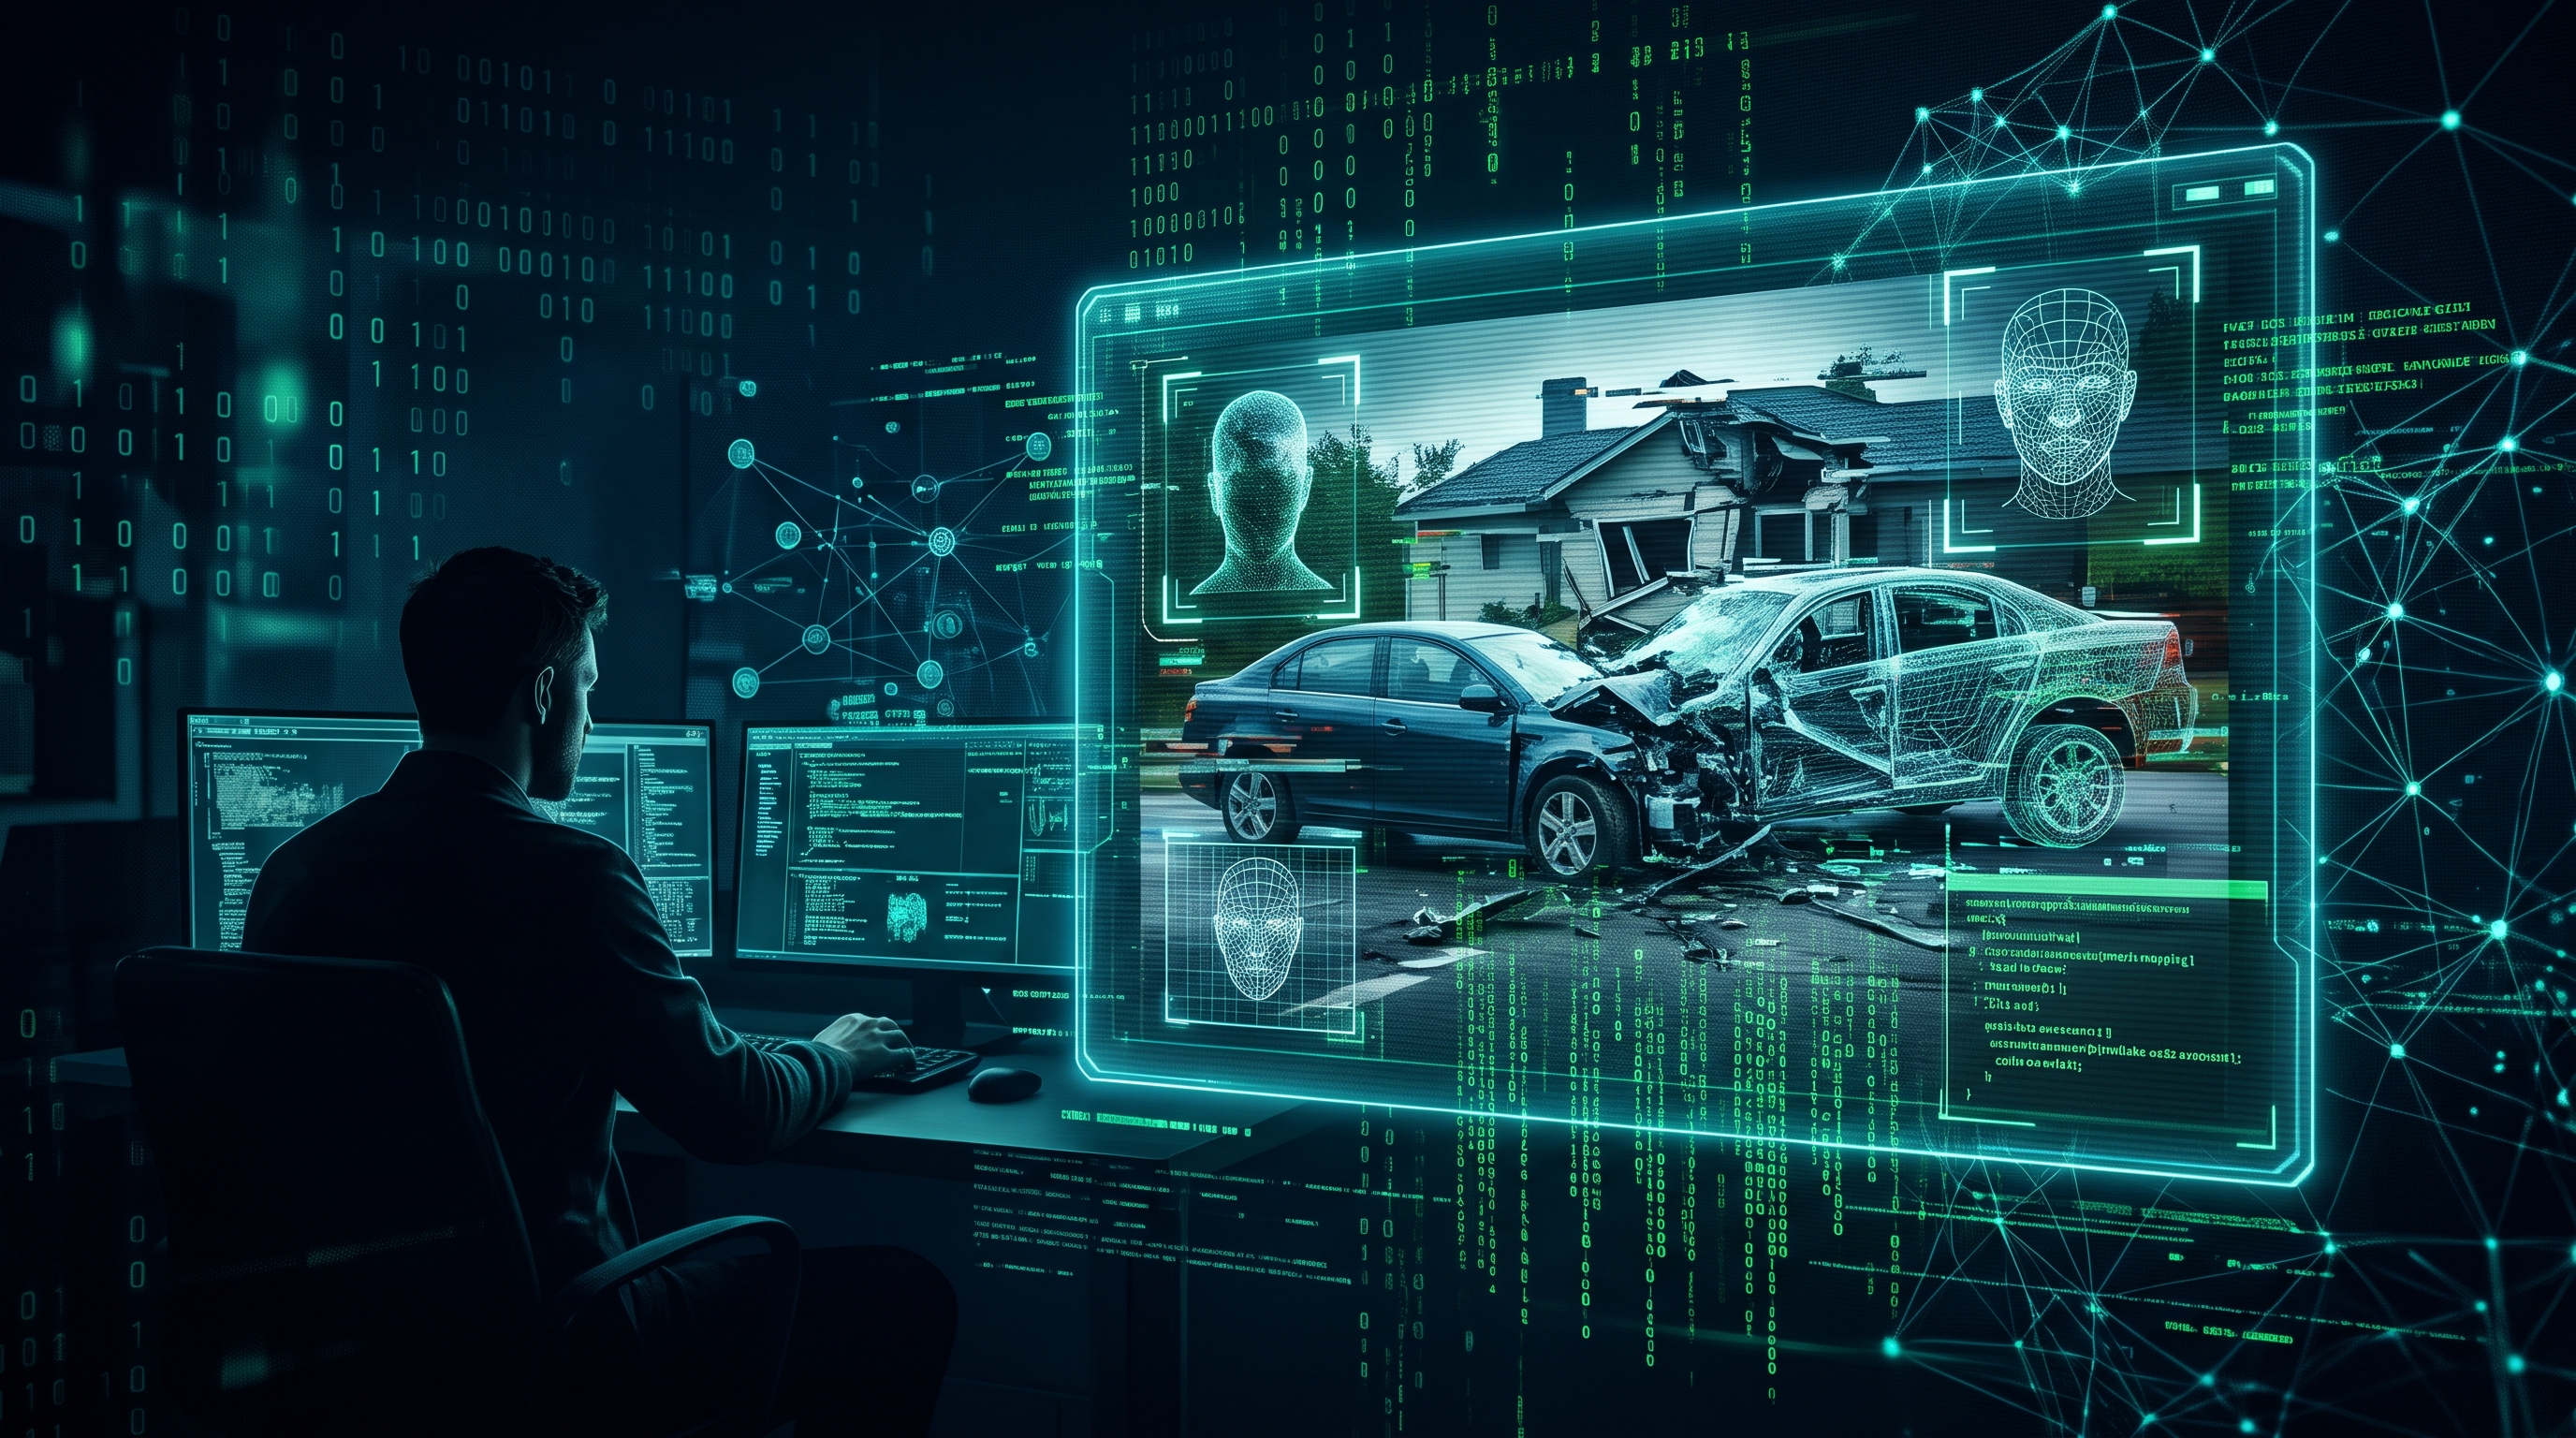

Remote claims assessment is the dominant model in 2026. Lemonade's AI Jim, Snapsheet's virtual appraisal platform, Tractable's auto and property damage AI, and the SightCall and Bdeo guided-inspection apps move hundreds of millions of claims through video and photo evidence without any adjuster ever standing in front of the asset. The operational gains have been real: claim cycle times measured in minutes rather than weeks, and straight-through settlement for the majority of low-severity loss events.
The same architecture is now the most exposed surface for synthetic video attacks in the insurance deepfake threat model. Text-to-video models released in 2026 (Sora 2, Veo 3.1, Kling 3.0) produce footage with correct hand anatomy, matched lighting, and lip-synced audio by default, and free face-swap tools can put a claimant's face and voice onto footage that was never theirs, according to UncovAI's September 2026 insurance claims analysis. FRISS's State of Insurance Fraud 2026 report found that 71% of practitioners identified "creating deepfake evidence (images, audio, video)" as a top AI weaponization vector against claims operations, while only 2% felt "very well prepared" for the agentic AI inflection point.
This guide walks through the five synthetic video attack vectors that target remote claims assessment specifically, where each one lands in the claims pipeline, and the detection stack that pushes back. It is written for SIU leads, claims transformation teams, virtual appraisal product managers, and carrier CTOs evaluating AI-driven claims platforms.
- Remote claims assessment platforms (Lemonade's AI Jim, Snapsheet, Tractable, SightCall, Bdeo, Monk.ai) process the majority of low-severity claims in 2026 with no physical inspection, creating a large synthetic-video attack surface.
- 2026 video generation models (Sora 2, Veo 3.1, Kling 3.0) produce footage that defeats manual adjuster review, according to UncovAI's September 2026 analysis of claim video deepfake signals.
- FRISS State of Insurance Fraud 2026: 71% of practitioners identified creating deepfake evidence (images, audio, video) as a top AI weaponization vector; only 2% felt very well prepared.
- Five synthetic video attack vectors operate against remote claims assessment in 2026: pre-recorded damage walkthroughs, real-time face swap on adjuster calls, camera injection against guided-capture apps, synthetic dashcam footage, and deepfake video statements aimed at AI triage.
- CheckFile.ai's 2026 guide classifies synthetic dashcam video as "high detection difficulty, early stage, accelerating," with Sora, Pika, and video diffusion models driving the quality curve.
- Human review is no longer a defense against modern video deepfakes; CheckFile.ai, UncovAI, and the FRISS report converge on this.
- Detection requires frame-level temporal analysis, physiological signal inspection, injection-attack detection at capture, and multi-modal risk scoring; no single technique is sufficient.
- The highest-leverage control shift is moving verification to the moment of capture rather than post-upload, aligned with ENISA's Remote ID Proofing good practices and the NAIC's 2025 guidance on AI-generated claim evidence.
What Is Remote Claims Assessment?
Remote claims assessment is any claims adjudication workflow where the damage, the loss event, or the claimant themselves is evaluated through digital media rather than in-person inspection. It covers three delivery modes that matter for the synthetic video threat model.
Pre-recorded video upload is the model Lemonade popularised. The claimant records a video explaining what happened, uploads it through the carrier's app, and an AI assistant (Lemonade's "Jim") analyses the recording alongside the policy data and makes an immediate decision or routes to a human reviewer. Snapsheet, Tractable, and Monk.ai operate variants of this pattern for auto and property claims.
Live video calls connect the claimant to a remote adjuster through a video conference or an AR-assisted platform. SightCall is the reference vendor for the AR-assisted variant, where the adjuster guides the claimant through showing specific angles and features of the damage. The adjuster sees the claimant's face and the asset in the same session.
Guided-capture inspection apps sit between the two. The carrier's app walks the claimant through a scripted set of photos or short videos (front of vehicle, each corner, under the hood, odometer, VIN plate), with on-device computer vision checking that each capture meets quality thresholds. DriveX, Bdeo, Ravin.ai, and the virtual appraisal modules of major carriers operate in this mode.
What ties the three modes together is that the evidence base entering the claims pipeline is video, captured at the claimant's end, delivered through the claimant's device. The adjuster, whether human or AI, inspects the pixels. They do not inspect the loss.
Why Synthetic Video Is the Attack of 2026
Three structural shifts have moved synthetic video from technical demonstration to production attack class against remote claims.
The first is generation quality. Through 2025, synthetic video routinely failed on basic signals: inconsistent lighting between frames, warped hands and teeth, physics violations in object motion, lip-sync drift against generated audio. 2026 models closed most of those gaps. UncovAI's September 2026 insurance analysis documents that current text-to-video models produce footage with correct hand anatomy, matched lighting, lip-synced audio, and consistent object physics by default. The signals that experienced adjusters learned to spot in 2024 have largely disappeared from the output of a 2026 generator.
The second is the collapse of human-review defense. Adjusters reviewing video at scale, under time pressure, with no reference to the physical scene, are structurally ill-equipped to catch high-quality synthetic footage. CheckFile.ai's 2026 US insurers guide, FRISS's 2026 practitioner survey, and UncovAI's manual-review-vs-detector comparison all converge on the same finding: visual inspection by humans is no longer a meaningful control against modern synthetic video. This is not a skill issue; it is a perception-limit issue that training cannot close.
The third is the automation of defense. AI-powered claim assistants that analyse submitted videos (Lemonade's AI Jim is the most-cited example, analysing tone, micro-expressions, and speech patterns) are themselves video-conditioned models operating on exactly the modality that generators now produce convincingly. A claim assistant trained to detect fraud on real video evidence is not inherently a deepfake detector, and in practice, dedicated deepfake detection and claim triage are different model classes.
The Five Synthetic Video Attack Vectors
1. Pre-Recorded Synthetic Damage Walkthrough
The dominant vector against Lemonade-style and Snapsheet-style video FNOL is a pre-recorded synthetic walkthrough. The attacker generates a video that appears to show a claimant moving around damaged property, narrating what happened, and framing specific damage features. The output is uploaded through the carrier's app or portal exactly as a legitimate video would be.
The quality of a 2026-era generation is sufficient to pass the visual inspection stage. The claim assistant, whether human or AI, sees damaged property, hears a claimant narrating, and triggers the standard adjudication pathway. For low-severity claims within the straight-through processing threshold, the fraudulent video can reach payment without any human ever looking at it.
Detection depends on signals humans cannot perceive at review speed: frame-level temporal consistency, generator-specific artefacts in the frequency domain, and inconsistencies between claimed capture device metadata and the actual video pipeline.
2. Real-Time Face Swap on Live Adjuster Video Calls
For SightCall-style live video sessions, the attack of choice is real-time face swap. The attacker drives the video call themselves but runs a consumer face-swap model that replaces their face, frame by frame, with the policyholder's face. The claimed policyholder's face is often constructed from a single reference photo scraped from social media, as covered in our analysis of generating deepfakes from a single photo.
The adjuster sees the policyholder speaking, responding to questions, turning their head on request, and showing the damaged asset. The face-swap preserves the attacker's motion and expression while substituting the identity. Active challenges that worked against 2022-era face-swap (asking the claimant to turn, blink, or cover part of their face) fail against modern real-time models.
This is the same technical class covered in our walkthrough of how fraudsters bypass KYC with deepfakes; the delivery pipeline is identical, only the business process on the other end differs.
3. Camera Injection Against Guided-Capture Apps
Guided-capture inspection apps (DriveX, Bdeo, Ravin.ai) assume the claimant is pointing their device camera at the actual asset. The app's on-device computer vision does quality checks on each required capture, but it treats the camera stream as trusted input from the device sensor.
Camera injection breaks that assumption. The attacker installs a virtual camera driver on a mobile device, runs the carrier's app, and feeds a pre-prepared synthetic video stream directly into what the app sees as the camera. The guided prompts complete successfully because the injected video has been produced with the specific angles the app will request (front of vehicle, left corner, right corner, odometer, VIN).
The attack surface extends to emulators running the mobile app on a desktop with full control of the input stream, and to API hooking of the capture SDK. Presentation attack detection in these apps was designed for photos at onboarding; it does not reliably catch stream injection on video capture.
4. Synthetic Dashcam and Incident Footage
Dashcam footage is a growing category of claim evidence, particularly in auto liability disputes where a video of the incident can resolve fault. Text-to-video models released in 2026 generate convincing dashcam-style footage of collisions, including correct physics of impact, debris, and vehicle motion.
CheckFile.ai's 2026 US insurers guide classifies synthetic dashcam video as "high detection difficulty, early stage, accelerating," specifically naming Sora, Pika, and video diffusion models as the production tooling. The guide notes that detection at this stage requires frame-level analysis rather than image-level deepfake classifiers.
The business impact is disproportionate because dashcam video often carries evidentiary weight in liability determinations and subrogation decisions. A single convincing synthetic dashcam clip can shift fault assignment on a claim and the subsequent recovery pursuit against another carrier.
5. Deepfake Video Statements to AI Claim Assistants
Lemonade's AI Jim analyses submitted claim videos for behavioural signals (tone, micro-expressions, speech patterns) in addition to policy data cross-reference. The intent is to catch deceptive claimants through behavioural inconsistency. In practice, this creates a specific attack target: a video deepfake calibrated to the behavioural signals the AI assistant is trained on.
Attackers with access to published descriptions of what an AI assistant evaluates (Lemonade is public about Jim's workflow) can tune generated video to present the expected signals: calm tone, consistent framing, reasonable detail density. The defense that AI-powered behavioural analysis would catch deepfakes assumes the two model classes are adversarial, but in practice the generator usually trains against an out-of-date version of the defender.
This category is still early, but the FRISS 2026 report's finding that 71% of practitioners identify deepfake evidence creation as a top AI weaponization vector is a direct signal that this intersection is where the attention is moving.
Where These Attacks Land in the Claims Pipeline
The synthetic video attack surface maps directly onto the operational pipeline of a modern remote claims program. Understanding which attack lands where is what determines whether a control investment actually closes a gap.
At First Notice of Loss, the exposure is pre-recorded synthetic damage video and pre-recorded video statements to AI assistants. This is also where the economic leverage is highest, because the straight-through processing threshold decides whether a claim is paid without human review. FRISS, CheckFile.ai, and the arXiv 2026 vehicle fraud survey all point to FNOL as the correct detection insertion point.
During live adjuster interaction, the exposure is real-time face swap. The attack happens inside the video conference, and the adjuster is actively engaged with what they believe is the policyholder. Catching this requires detection running on the stream in real time, with low enough latency to flag mid-call, which is a materially harder operational problem than post-upload analysis.
During guided virtual inspection, the exposure is camera injection. The claimant's device is the attack surface, and the mobile SDK is what either catches or misses the injection. Capture attestation (verifying that the stream came from the physical camera rather than a virtual source) is the control family that addresses this, and it is the same control that matters for injection attacks at KYC, as we covered in the five vectors fraudsters use to bypass KYC.
During AI-based claim triage, the exposure is deepfake video calibrated to fool the specific behavioural model in use. The defense here is to treat the triage model as insufficient on its own for fraud detection, and to layer a dedicated deepfake media classifier alongside it.
Why Standard Fraud Controls Miss Synthetic Video
Four structural gaps explain why remote claims assessment is systematically exposed to synthetic video in 2026, even in carriers that have been thoughtful about deepfake risk on other channels.
Human review is the most-cited control that no longer works. CheckFile.ai, UncovAI, and FRISS all document the same finding: experienced adjusters cannot reliably distinguish 2026-era synthetic video from authentic footage during normal review workflows. This is not a training problem. The perceptual differences have been engineered out of the output of current generators, and the time budget of a routine claim review does not include the second-by-second scrutiny that might catch residual artefacts. Treating a human adjuster as a last line of defense is a controls posture built for 2022.
Image-only detection misses the strongest video signals. Many "deepfake detection" products in the market are image classifiers that score each frame independently. Synthetic video carries much stronger evidence in temporal signals (frame-to-frame consistency, motion continuity, blink and gaze dynamics, physiological rhythm) than in any single frame. A detection stack built from a single-frame classifier underperforms badly against modern video generators.
Device attestation gaps in mobile SDKs. The guided-capture inspection apps that are now standard in auto and property claims mostly assume the device camera is the camera, without cryptographic attestation of the capture source. ENISA's Remote ID Proofing Good Practices and the broader injection attack detection literature flag this as the structural weakness of mobile claims capture in 2026.
Cross-claim detection comes too late. Verisk's cross-carrier image database and similar industry reference data catch coordinated fraud by matching duplicate or near-duplicate evidence across claims and carriers. For synthetic video, the attacker generates unique content for each claim, so cross-carrier matching has no signal. The defense needs to catch the generator's statistical fingerprint on first upload, not wait for the second claim to notice the pattern.
How to Detect and Stop Synthetic Video in Claims
A resilient remote claims program in 2026 runs five detection techniques in parallel across the claims pipeline, with risk-scored routing to human review for borderline results.
Temporal frame-level analysis inspects the video across time, not frame by frame. It catches inconsistencies in motion, lighting transitions, object physics, and blink and gaze patterns that single-frame classifiers miss. This is the single most important defense against 2026-era generators, which are strongest at individual-frame fidelity and weakest at long-sequence consistency.
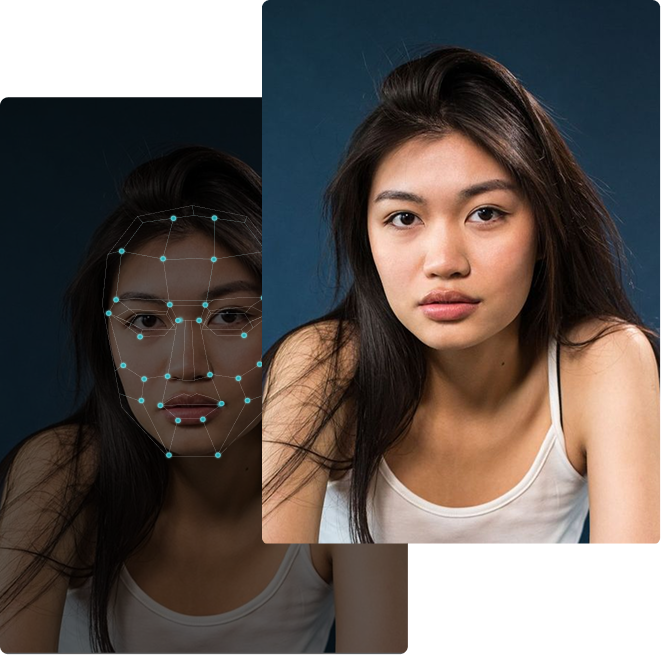
Physiological signal detection looks for the passive biological signals that a real person's face produces and a generator usually does not (blood-flow colour variation, subtle micro-expression patterns, consistent 3D depth across head poses). The gap between generator output and these signals is narrowing but still exploitable, and it carries detection value that is independent of generator-specific pixel artefacts.
Injection attack detection at capture addresses the guided-inspection camera-injection vector directly. The mobile SDK has to verify that the stream it is processing originated from the device's physical camera, not a virtual camera driver, emulator, or hooked API. This is the same control family that KYC vendors are now building out, and the technical approach transfers directly to insurance claims capture.
Capture attestation and C2PA content credentials extend the injection-detection principle to post-capture provenance. C2PA (Content Authenticity Initiative) is embedded in an increasing number of capture devices and editing tools, and the absence of credentials on a claim video is an informative risk signal even where present credentials cannot be fully verified.
Multi-modal risk scoring ties the detection outputs to policy, behavioural, and historical signals. A video that scores 40% suspicious on a classifier plus a claim submitted 10 minutes after policy inception from a device that has never logged in before is a different risk profile from a 40% score on an established policyholder with twelve months of clean history. The right decision is a risk-scored routing to human review, not a binary pass/fail on the detector alone.
DuckDuckGoose publishes video detection accuracy specifically against unseen generators, which is the operational signal claims teams need: not "does the detector catch Sora 2 outputs" but "does the detector catch the generator the next attacker will use."
Common Mistakes
Three mistakes recur in remote claims programs that have otherwise invested seriously in digital fraud controls.
Running an image-only deepfake detector on video inputs. Most products marketed for "image deepfake detection" score frames independently and miss the temporal signals that carry the strongest evidence against 2026 video generators. Procurement should explicitly ask whether a vendor's video detection is a frame-level classifier wrapped in a video loader, or a model trained on temporal signals.
Assuming the live video adjuster is a defense. A human on a video call is not a face-swap detector. The value a live adjuster adds is unpredictable questioning, scene context, and the ability to request odd specific angles the attacker's generator may not have been trained on. Scripted video adjuster processes with fixed challenge sets are not meaningfully more secure than automated flows against a prepared attacker.
Treating capture attestation as optional. Camera injection against mobile capture SDKs is the dominant 2026 attack path on guided inspections, and SDKs built before injection attack detection was a procurement requirement typically do not stop it. Carriers running virtual inspection on 2023-era SDKs should assume injection is not caught.
Practical Recommendations
A pragmatic 2026 roadmap for remote claims programs has four priorities.
Insert detection at the moment of capture or upload, not post-adjudication. The economics of straight-through processing collapse if fraudulent claims are only caught on re-review after payment. Detection running synchronously on the upload path, with risk-scored routing for suspicious results, preserves the speed benefit of digital claims while rebuilding the integrity base.
Build a temporal video detection capability. Frame-level temporal analysis is the single most important technical gap in most carrier fraud stacks today. If your current detection stack scores video as a sequence of independent frames, it is not meeting the 2026 threat profile.
Add injection attack detection to the guided-inspection SDK. Virtual inspection apps that assume the camera stream is trusted are the direct analogue of KYC liveness systems that assume the same thing. Both fail against camera injection, and both need the same architectural fix.
Treat AI claim assistants as triage, not as fraud detection. Lemonade-style AI assistants are optimised for claim triage efficiency, not for synthetic video detection, and the two are not the same model class. A dedicated deepfake classifier running in parallel, with explicit coverage of video-generator outputs, closes the gap that a triage model does not.
DuckDuckGoose's DeepDetector is designed specifically for the video deepfake detection problem these recommendations address, with model performance tested against generators the detection system has not been trained on.
Frequently Asked Questions
Can human adjusters catch 2026-era synthetic video in claim reviews?
Not reliably. CheckFile.ai's 2026 US insurers guide, UncovAI's September 2026 analysis, and the FRISS State of Insurance Fraud 2026 report all document that modern text-to-video models produce footage with correct hand anatomy, matched lighting, lip-synced audio, and consistent physics. The visual cues experienced adjusters learned to use in 2024 have largely been engineered out of 2026 generator output.
Which remote claims platforms are most exposed to synthetic video fraud?
Any platform that relies on video evidence captured at the claimant's end: Lemonade-style AI-assisted video FNOL, SightCall-style live video adjuster calls, and guided-capture inspection apps including Snapsheet, Tractable, DriveX, Bdeo, and Monk.ai. The exposure is not a weakness of these platforms specifically; it is a feature of the remote-first architecture they all share.
What is camera injection and why does it matter for virtual inspection?
Camera injection is an attack in which the attacker installs a virtual camera driver on a mobile device (or runs the app in an emulator) and feeds a pre-prepared synthetic video stream directly into what the inspection app sees as the camera. The guided prompts complete successfully because the injected video has been prepared with the specific angles the app will request. Standard presentation attack detection does not catch injection, because the attack happens upstream of the sensor.
Is C2PA enough to verify authentic claim video?
Not on its own, but it is a meaningful signal. C2PA (Content Authenticity Initiative) credentials embedded by capture devices and editing tools can be inspected by claims systems to verify provenance where present. Absence of credentials, or modified credentials, is an informative risk signal. Full verification of C2PA chains requires that both the capture device and the processing pipeline support the standard, which is still partial in 2026.
How should carriers evaluate deepfake video detection vendors for claims?
Three independent test categories: temporal video deepfake detection on outputs from 2026 generators (Sora 2, Veo 3.1, Kling 3.0 class), injection attack detection on mobile capture (virtual camera, emulator, API hook), and generalisation to unseen generators the vendor has not explicitly trained on. Confirm the model refresh cadence, which should be measured in weeks for the generation side to keep pace.
Does Lemonade's AI Jim or a similar claim assistant catch deepfake video?
Not as its primary function. AI claim assistants are optimised for triage efficiency and behavioural signal analysis across the claim as a whole, not for detecting synthetic media specifically. They are a useful layer, but they are not substitutes for dedicated deepfake detection. Carriers running AI-first triage should layer a dedicated video deepfake classifier alongside it.
What is the single highest-leverage control shift for 2026?
Move verification to the moment of capture, with injection attack detection on the mobile SDK and temporal video analysis on upload. This is the architectural equivalent of the shift KYC programs are making in response to the same technical class of attack, and it preserves the straight-through processing economics that make remote claims assessment viable.
How do regulators view synthetic video fraud in claims?
The NAIC issued specific guidance on AI-generated claim evidence in 2025, and 43 US states carry mandatory SIU requirements under NAIC model legislation. State DOI audits are moving toward scrutinising whether carrier systems treat AI-generated fraud as a named risk category. At EU level, ENISA's Remote ID Proofing Good Practices and the EU AI Act Article 50 transparency requirements for AI-generated content set a related expectation.
About the author