









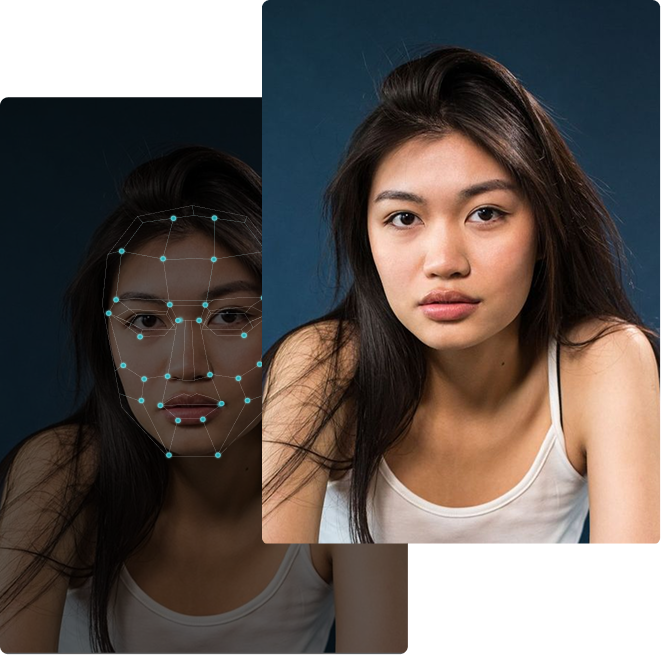


Challenge-response is the active form of liveness detection, the step that asks you to blink, turn your head, smile, or read a random phrase, and checks that you do it. For years it was considered the stronger kind of liveness, on a simple and sound logic: a photo or a pre-recorded video cannot respond to an unpredictable instruction in real time. Against a live deepfake, that logic breaks, but not completely, and the nuance is where the useful story is.
This piece is an honest assessment of how challenge-response tests hold up against real-time deepfakes: what the tests are and why they were thought robust, how live face swaps defeat the standard ones, which harder challenges still expose a fake and which do not, the costs, and how to use challenge-response so that it actually contributes to a defense. It is written for the fraud, identity, and security teams deciding how much to trust the challenge in their verification flow.
The one-line verdict is that performing an action on cue is exactly what a real-time face swap is good at, so blink-turn-smile no longer proves much. But not all challenges are equal, and the ones that are hardest to fake, combined with the right supporting detection, still have a role.
- Challenge-response, or active liveness, asks a user to perform a randomized action in real time, and it was long considered the stronger liveness test because a pre-recorded fake cannot respond on cue.
- Live deepfakes break that logic: a real-time face swap is driven by a human who performs the challenge, so it blinks, turns, and smiles when asked.
- The very interactivity that made active liveness strong now gives a deepfake a script to follow, and an injected stream can carry the responsive fake past the camera.
- Not all challenges are equal: a 2026 study found pose and combined gestures expose real-time swaps best, while facial expressions add little, and hand occlusion is unreliable against tools built to mask it.
- Real-time face swaps degrade at extreme head angles beyond roughly 70 degrees, dynamic occlusion where a hand crosses the face, and fast or emotional speech where audio and lips drift.
- Response latency is a useful tell, because real-time rendering adds delay that a tightly timed challenge can expose.
- The honest verdict is that standard blink-turn-smile challenges are defeated, harder challenges raise the bar without closing the gap, and active liveness adds friction.
- Challenge-response is most valuable as one signal within layered detection; the strongest results pair randomized challenges with passive deepfake detection and injection detection.
What Challenge-Response Testing Is
Challenge-response, or active liveness, works by issuing a prompt and verifying the reaction. The system asks the user to perform a randomized action, a blink, a head turn, a smile, following a moving target with their eyes, or reading aloud a random sequence of digits, and confirms in real time that the response matches what was asked. The randomization is the whole security idea: a pre-recorded deepfake cannot answer an arbitrary instruction it did not know in advance, so a system that demands an unpredictable action should, in principle, filter out anything that was not captured live.
For the attacks it was designed for, this works. A printed photo cannot blink, a video replayed from a phone cannot respond to a prompt it has never seen, and a static mask cannot smile on cue. Against that class of presentation attacks, active challenge-response is genuinely strong, which is why it became the default upgrade over passive liveness in high-assurance flows and why it was long regarded as the more secure option. The trouble is that the threat model moved, and the newer attacks do respond.
Why Live Deepfakes Defeat Standard Challenges
The defeat is mechanical, not clever. A real-time face swap maps a synthetic face onto the live movements of the attacker driving it, so when the system says "blink," the attacker blinks and the swapped face blinks with them; when it says "turn left," they turn and the fake turns too. As one analysis put it bluntly, a real-time face-swap model blinks when asked and turns when asked, because responding on cue is exactly what a generative model driven by a live person does well. The randomization that was supposed to be the defense becomes the problem: the very interactivity that made active liveness strong now hands the deepfake a script to follow, since the prompt tells the attacker precisely what motion to perform.
Injection closes the loop. The attacker runs the responsive face swap on a consumer graphics card and routes it into the verification app through a virtual camera, so the challenge-response exchange happens normally while the "camera feed" is a synthetic stream that obeys every instruction. The result is that a live human wearing a fake face satisfies a test designed to prove a live human is present, which it truthfully is, while telling the system nothing about whether the face is real. This is documented formally, including a MITRE ATLAS case study of an attack that evaded both passive and active liveness, and it is why challenge-response on its own can no longer be treated as sufficient.
What Still Holds, and What Doesn't
Here is where the blanket verdict is wrong and the nuance matters: not all challenges are equal. A 2026 study that tested randomized gesture challenges across more than a hundred live sessions against real-time face-swap tools injected through a virtual camera found that challenges genuinely add detection value when paired with a passive detector, lifting session-level performance well above a static baseline. But the gain depended heavily on the gesture. Pose changes and combined or sequential gestures exposed the swaps best, while facial expressions like smiling showed no clear improvement, and hand occlusion was unreliable, scoring below the static baseline against a tool specifically configured to mask occlusions. In other words, asking someone to smile proves almost nothing, but asking for an awkward, compound movement proves more.
The practical pattern, consistent across the research and the field, is that real-time face swaps degrade at the edges of what they were trained to render. Strong profile turns past roughly seventy degrees, extreme upward or downward head angles, dynamic occlusion where a hand or document crosses the face and the blended edges smear, and fast or emotional speech where audio and lip movement drift apart all tend to expose synthesis errors a simple blink never would. Response latency is a further tell, because the real-time rendering pipeline adds delay, so a tightly timed challenge can catch the lag. The honest conclusion is that harder, unpredictable, pose-and-occlusion-based challenges raise the bar meaningfully, while the standard blink-turn-smile set is largely defeated, and even the hard challenges are an arms race, since tools are already adding occlusion handling.
The Costs: Friction and a Predictable Script
Challenge-response is not free, and its costs weigh against its shrinking benefit. Every action a system demands adds friction, and friction drives onboarding abandonment, so a flow heavy with challenges loses legitimate users precisely to defend against an attack that the easy challenges no longer stop. There is also the script problem: if a system draws from a small, fixed set of challenges, an attacker quickly learns the repertoire and prepares for all of it, which is why a genuinely unscripted, varied, and randomized element matters far more than the mere presence of a challenge. And the whole thing is adversarial, so any specific hard challenge that becomes standard is one the next generation of tools will be trained to handle.
None of this makes challenge-response worthless. It still stops the low-effort attacks it was built for, and the hard variants still contribute signal. But it does mean challenge-response cannot be the control that decides whether a real face is in front of the camera, because a competent real-time deepfake will pass the easy parts and may pass the hard parts, all while the user experience degrades for everyone genuine.
The Fix: Pair Challenge-Response with Deepfake Detection
The most important finding from the research is also the most useful for practice: the strong results came not from challenges alone but from challenges combined with a passive detector that analyzes the media itself. That is the template. Challenge-response should be treated as one signal within a layered system, not as a standalone gate, and the layer that does the heavy lifting is dedicated deepfake detection, which asks a different question entirely: is this face synthetic, regardless of whether it performed the requested action. A detector reading the statistical signatures of synthetic generation catches the real-time swap that blinked and turned perfectly on cue, because it is not grading the performance, it is examining the pixels. Injection detection adds the check that the feed came from a real camera rather than a virtual one.
This is the role DuckDuckGoose, based in Delft, is built for. DeepDetector analyzes images and video for the signatures of synthetic media, catching the live face swaps that satisfy a challenge, with explainable output and ISO 27001, SOC 2, and GDPR compliance, and it complements rather than replaces the liveness and challenge-response a verification flow already runs. Used together, challenge-response filters the low-effort attacks and contributes pose and latency signals, while detection answers the question the challenge cannot. For the broader picture of why liveness alone falls short, see our guide to why liveness checks fail against deepfakes, and for the injection vector that carries the responsive fake into the pipeline, how injection attacks feed deepfakes into verification.
Frequently Asked Questions
What is a challenge-response liveness test?
It is an active liveness check that prompts the user to perform a randomized action, such as blinking, turning the head, smiling, following a target, or reading a random phrase, and verifies the response in real time. The idea is that a pre-recorded fake cannot answer an unpredictable instruction, so the test should prove a live person is present.
Can a deepfake pass a challenge-response test?
Yes, if it is a real-time deepfake. A live face swap is driven by a human who performs the requested action, so it blinks, turns, and smiles on cue, and when injected through a virtual camera it satisfies the challenge while showing a synthetic face. Standard blink-turn-smile challenges are largely defeated by competent real-time tools.
Are some challenges better than others against deepfakes?
Yes. Research shows pose changes and combined or sequential gestures expose real-time swaps best, while facial expressions like smiling add little, and hand occlusion is unreliable against tools built to mask it. Real-time swaps degrade at extreme head angles, dynamic occlusion, and fast speech, so harder, unpredictable challenges raise the bar, though they do not close the gap alone.
Why did active liveness used to be considered stronger?
Because a photo or pre-recorded video cannot respond to an unpredictable instruction in real time, so challenge-response reliably filtered out those presentation attacks. That logic held until real-time face-swap tools made it possible to perform the requested actions live, turning the interactivity that was its strength into a script an attacker can follow.
Does challenge-response add friction?
Yes, and that is part of the trade-off. Asking users to perform actions increases onboarding abandonment, so a challenge-heavy flow loses legitimate users while a competent real-time deepfake still passes the easy challenges. This friction-for-limited-benefit balance is why challenge-response should be one signal among several rather than the primary control.
Can response latency reveal a deepfake?
It can help. Real-time face-swap rendering adds processing delay, so a challenge timed tightly can expose the lag between the prompt and a natural response. Latency is a useful complementary signal, measured and scored rather than left to a human observer, but like individual gestures it is one input, not a complete test on its own.
How should challenge-response be used in 2026?
As one layer, not the gate. Pair it with passive deepfake detection that analyzes whether the face is synthetic regardless of the challenge, and with injection detection that confirms the feed came from a real camera. Keep a genuinely unscripted, randomized element with pose and occlusion, log latency and movement, and let dedicated detection answer the question the challenge cannot.
About the author